How Paystack uses monitoring and observability to keep payments reliable
A behind-the-scenes look at the engineering practices, tools, and automation helping us detect problems, understand their impact and respond
A successful payment at Paystack depends on several systems working together. Behind the confirmation a customer sees, processing that payment can involve Cloudflare, an API gateway, internal services, databases, queues, payment processors, and banks.
Each dependency introduces a potential point of failure. A slow database query, a growing queue backlog, or a timeout from a payment processor can delay or interrupt a transaction. For businesses that rely on Paystack, these issues can mean missed sales, incomplete transfers, or delayed settlements.
When something goes wrong, our engineers need to identify where the problem is happening, understand which businesses and transactions are affected, and determine how to restore service. In a system with this many dependencies, detecting a failure is only part of the challenge. We also need enough context to investigate its cause.
That’s the role monitoring and observability play at Paystack, and the work begins before a service reaches production.
In this article, we’ll walk through our approach, from defining monitoring requirements in a technical specification to alerting the engineer on call and investigating an incident. We’ll also look at SWAN, our internal automation system, and Sherlock, an AI-powered tool that helps engineers investigate incidents faster.
Monitoring helps us detect problems. Observability helps us investigate them.
To understand how a service behaves in production, we first need to instrument it: add the code and configuration that emit data about its operation.
That data includes:
- Metrics, which measure behavior over time, such as request latency and transaction success rates.
- Logs, which record individual events, errors, and their context.
- Traces, which capture the path and timing of a request across services.
Monitoring uses these signals to track system health. We monitor transaction success rates, error rates, latency, request volume, queue depth, and database connections. When a signal meets a defined alert condition, such as an error rate exceeding a threshold for a sustained period, it can trigger an alert for an engineer to investigate.
Observability is our ability to understand a system’s internal behavior through the data it produces. Engineers use that data to investigate both familiar failure patterns and problems they haven’t anticipated.
For example, monitoring might flag an increase in payment latency. An engineer could then examine traces to locate where requests are spending time, inspect logs for errors, and compare metrics across the affected services to narrow down the cause. The quality of that investigation depends on how well we’ve instrumented the system and whether we can connect signals across its components.
Alerting brings the right engineer into that investigation, while automation can take predefined corrective actions without waiting for someone to intervene.
Together, these practices form a continuous cycle:
Instrument → Observe → Detect → Respond → Learn
We instrument services to produce useful data, observe their behavior, detect potential problems, and respond through investigation or automated corrective actions. What we learn feeds back into how we build and instrument those services.
At Paystack, that cycle begins before a service goes live.
Observability starts in the technical specification
Every new Paystack service or significant feature begins with a technical specification. This document explains what the service should do, how it will interact with other systems, and the decisions behind its architecture. It also includes a dedicated observability section.
Before development begins, engineers must answer questions such as:
- How will we know whether the service is healthy?
- Which metrics reflect merchant and transaction outcomes?
- Which failures should trigger an alert, and who owns the response?
The engineers building the service define these requirements, with input from product owners, principal engineers, and the Platform and Observability teams.
During development, engineers add the instrumentation needed to produce those signals. To make this consistent across teams, Paystack’s Platform team maintains an internal observability package for NestJS services. Installed as a standard npm dependency, it initializes OpenTelemetry tracing, structured logging, and baseline metrics.
The package gives these services a common starting point. Engineers still need to define and instrument the signals that reflect how their particular product works.
For example, baseline metrics might show that a transfer endpoint is responding successfully. But accepting a transfer request doesn’t mean the transfer has completed. Engineers also need to track whether transfers move from pending to success. For a cross-border payments service, they may need to measure how long each external partner takes to return an exchange rate.
These product-specific signals connect application behavior to the outcomes businesses depend on.
Engineers validate the telemetry as they build, checking that traces are generated, logs contain the context needed for investigation, and metrics change as expected. They test the instrumentation again in staging before deployment.
When the service goes live, monitors and alerts are activated with clear response ownership. Engineers may also add automation rules for failure scenarios that can be handled safely without manual intervention.
This preparation gives us a foundation for assessing both the service’s technical health and the payment experience it supports.
Monitoring the payment experience
A healthy server doesn’t always mean a healthy payment experience. To understand whether payments are working as intended, we monitor four connected layers:
- Service health: latency, errors, throughput, resource usage, database health, and processing queues.
- Transaction health: whether payments and transfers are initialized, pending, successful, failed, reversed, or taking too long to complete.
- External dependencies: the performance of banks, gateways, card networks, and processors.
- Merchant impact: success rates, availability, settlement health, and performance across channels, markets, and merchant groups.
Together, these layers help engineers locate a problem and decide how to respond. An internal failure may require a deployment rollback or configuration change. A degraded payment partner may require a routing change or communication to affected merchants.
Get more stories like this
Subscribe to our newsletter to receive updates when new articles go live on the Paystack Blog.
Subscribe hereHow transfer monitoring has evolved
For outbound transfers, we track each transfer from initialization through pending, success, or failure. This lets engineers see whether transfers are completing normally across banks and gateways.
If success rates through one partner fall, transaction and dependency metrics help identify the affected routes, any increase in pending transfers, and changes in response times.
Over time, the team has made this view more granular. Early monitoring could filter transfer health by bank, gateway, and transaction type. Later instrumentation added merchant-level context, helping engineers distinguish a widespread incident from one affecting a smaller group.
That precision comes with a trade-off. In a metrics system, each unique combination of label values can create a separate time series. Adding a dimension with many possible values, such as a merchant identifier, can substantially increase the number of series the system stores and queries. This is a metric’s cardinality.
Higher cardinality can increase storage, processing costs, and query complexity. We therefore need to choose dimensions deliberately, preserving the context engineers need to assess impact without collecting every possible combination.
As we learn how services behave in production, we refine that instrumentation. For some failure patterns, the resulting signals are also precise enough to support an automated response.
SWAN: From detection to containment
At Paystack, a gateway is a path through which a transaction or transfer can be processed.
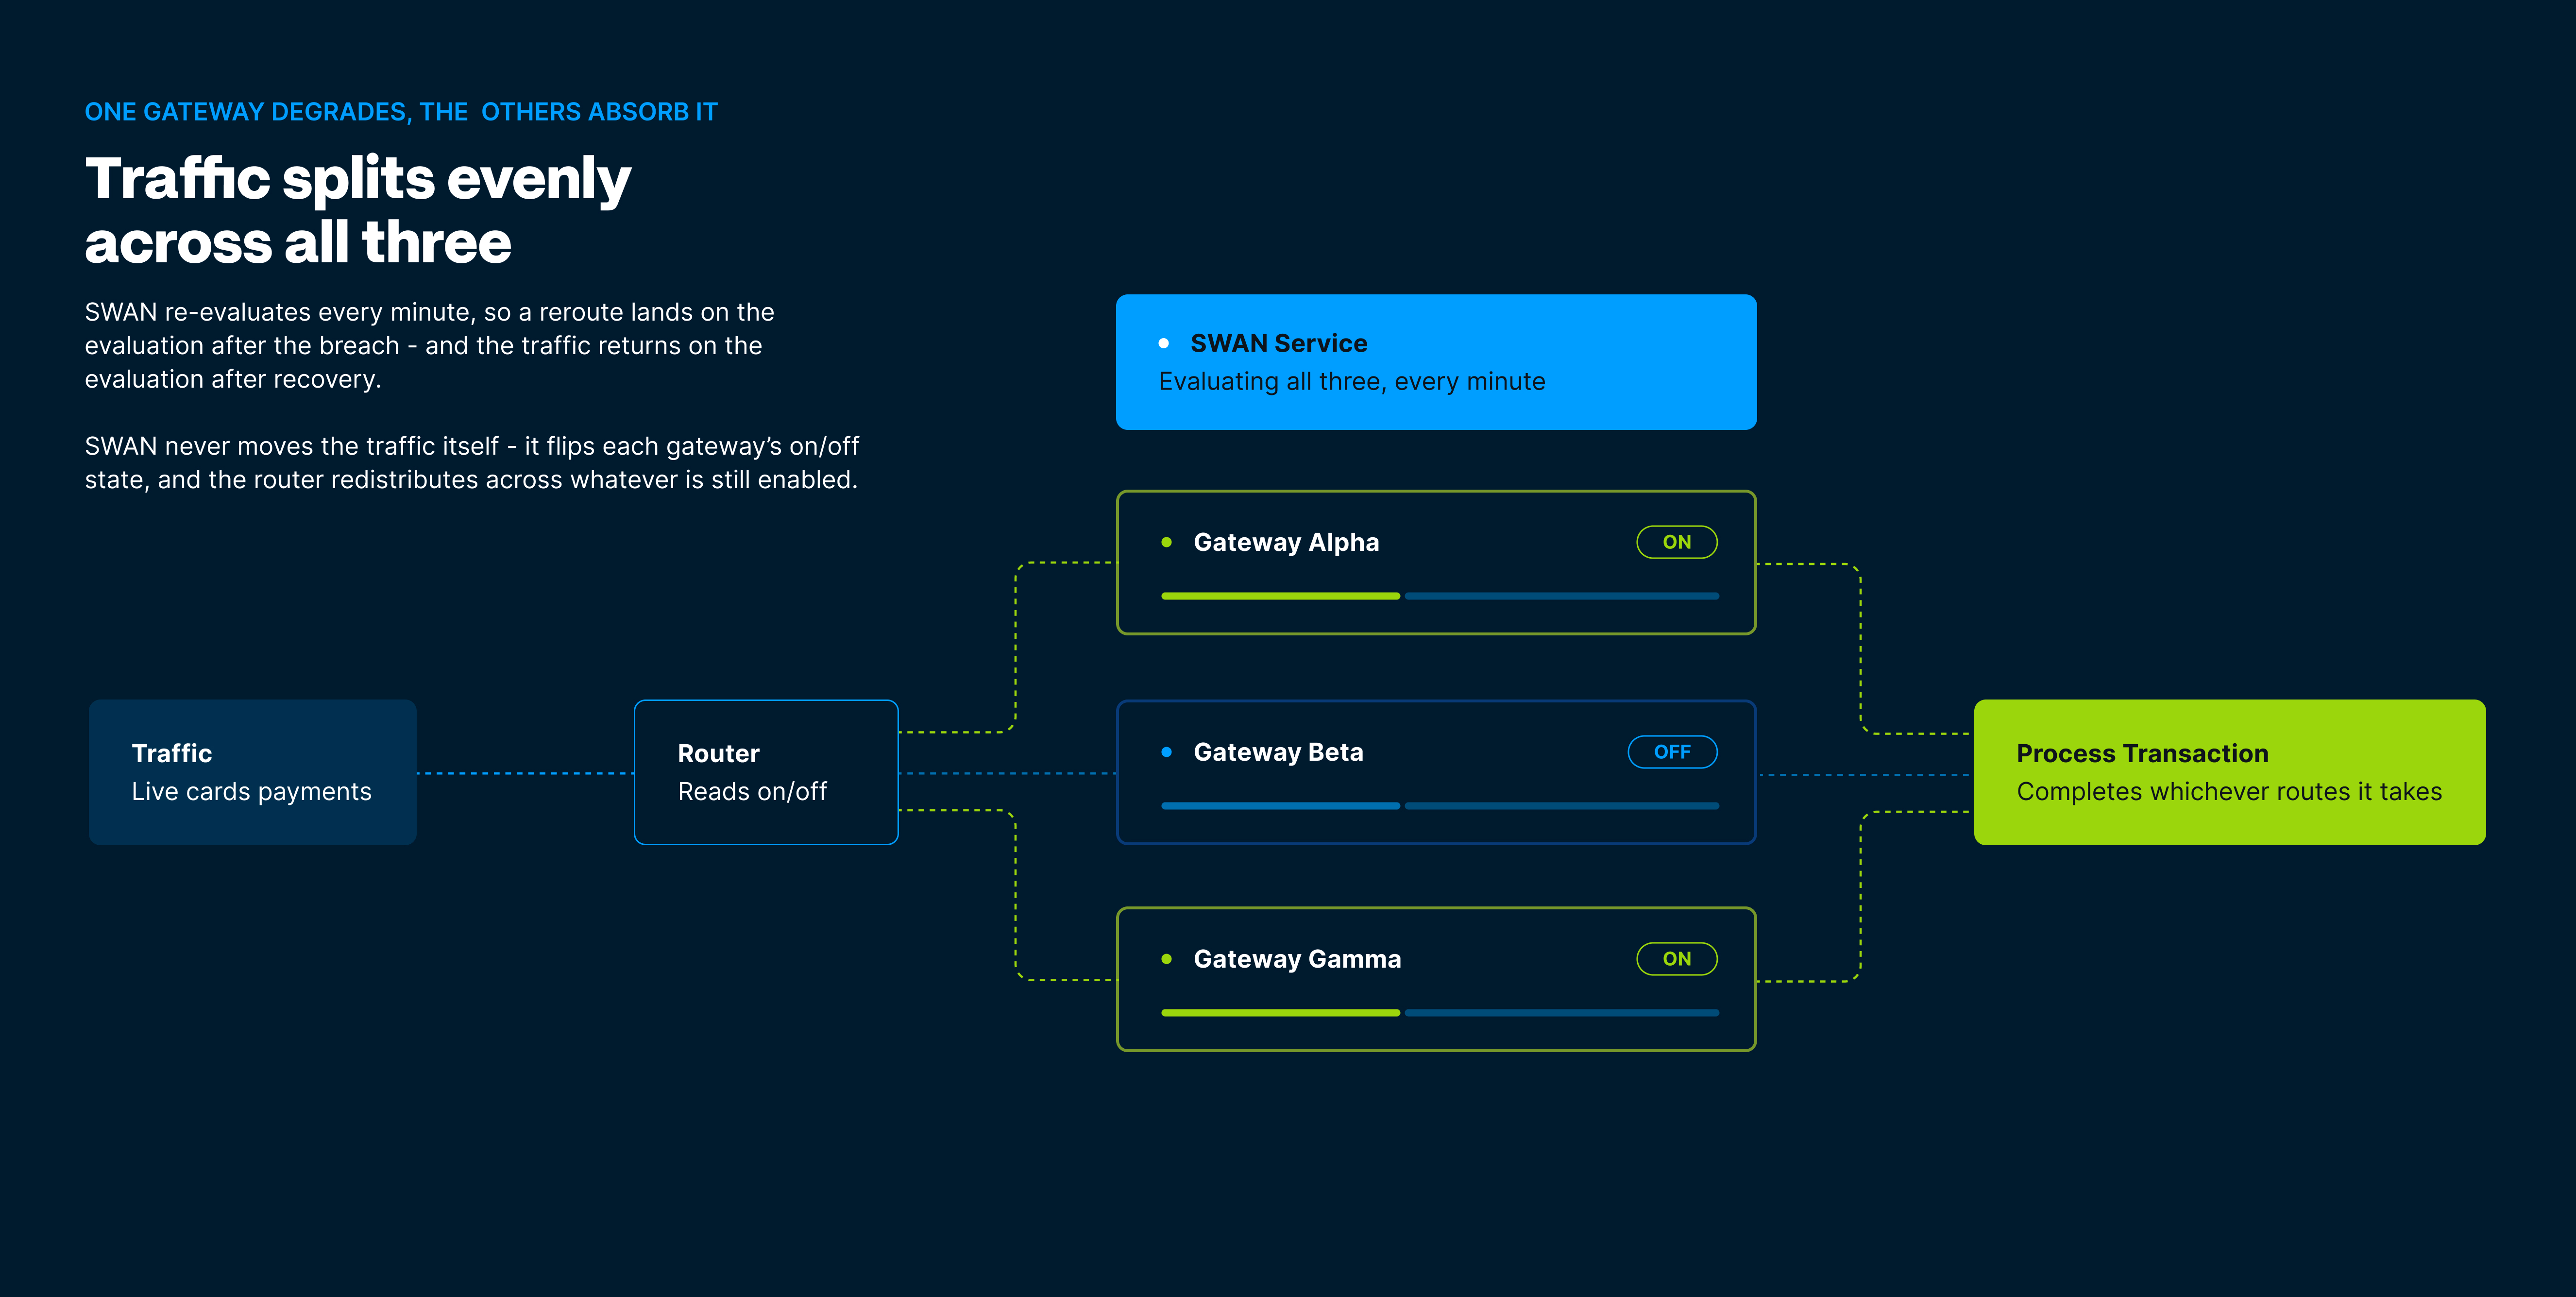
Each gateway has a processing partner and rules describing which transactions it can handle. When several gateways are eligible, our routing system ranks them and selects the highest-ranked option.
If a transaction fails, the routing system can retry it through another eligible gateway. But when a gateway experiences an outage, new transactions can continue reaching it because the routing rules still rank it first. Those transactions fail before either being retried elsewhere or returning an error to the customer.
In our early days, engineers could manage these incidents by manually changing the routing configuration. As the number of gateways grew, that became harder to sustain.
We built SWAN, short for Sleep Well At Night, to automate that response. It evaluates gateway health and can mark a failing gateway as unavailable, removing it from the routing path.
Evaluating gateway health
SWAN represents each gateway as a monitor. Its configuration defines:
- The data source and signal to evaluate
- The evaluation window and minimum transaction count
- The threshold for taking action
- The minimum disablement period
- The escalation period
- The actions to run when enabling or disabling a gateway
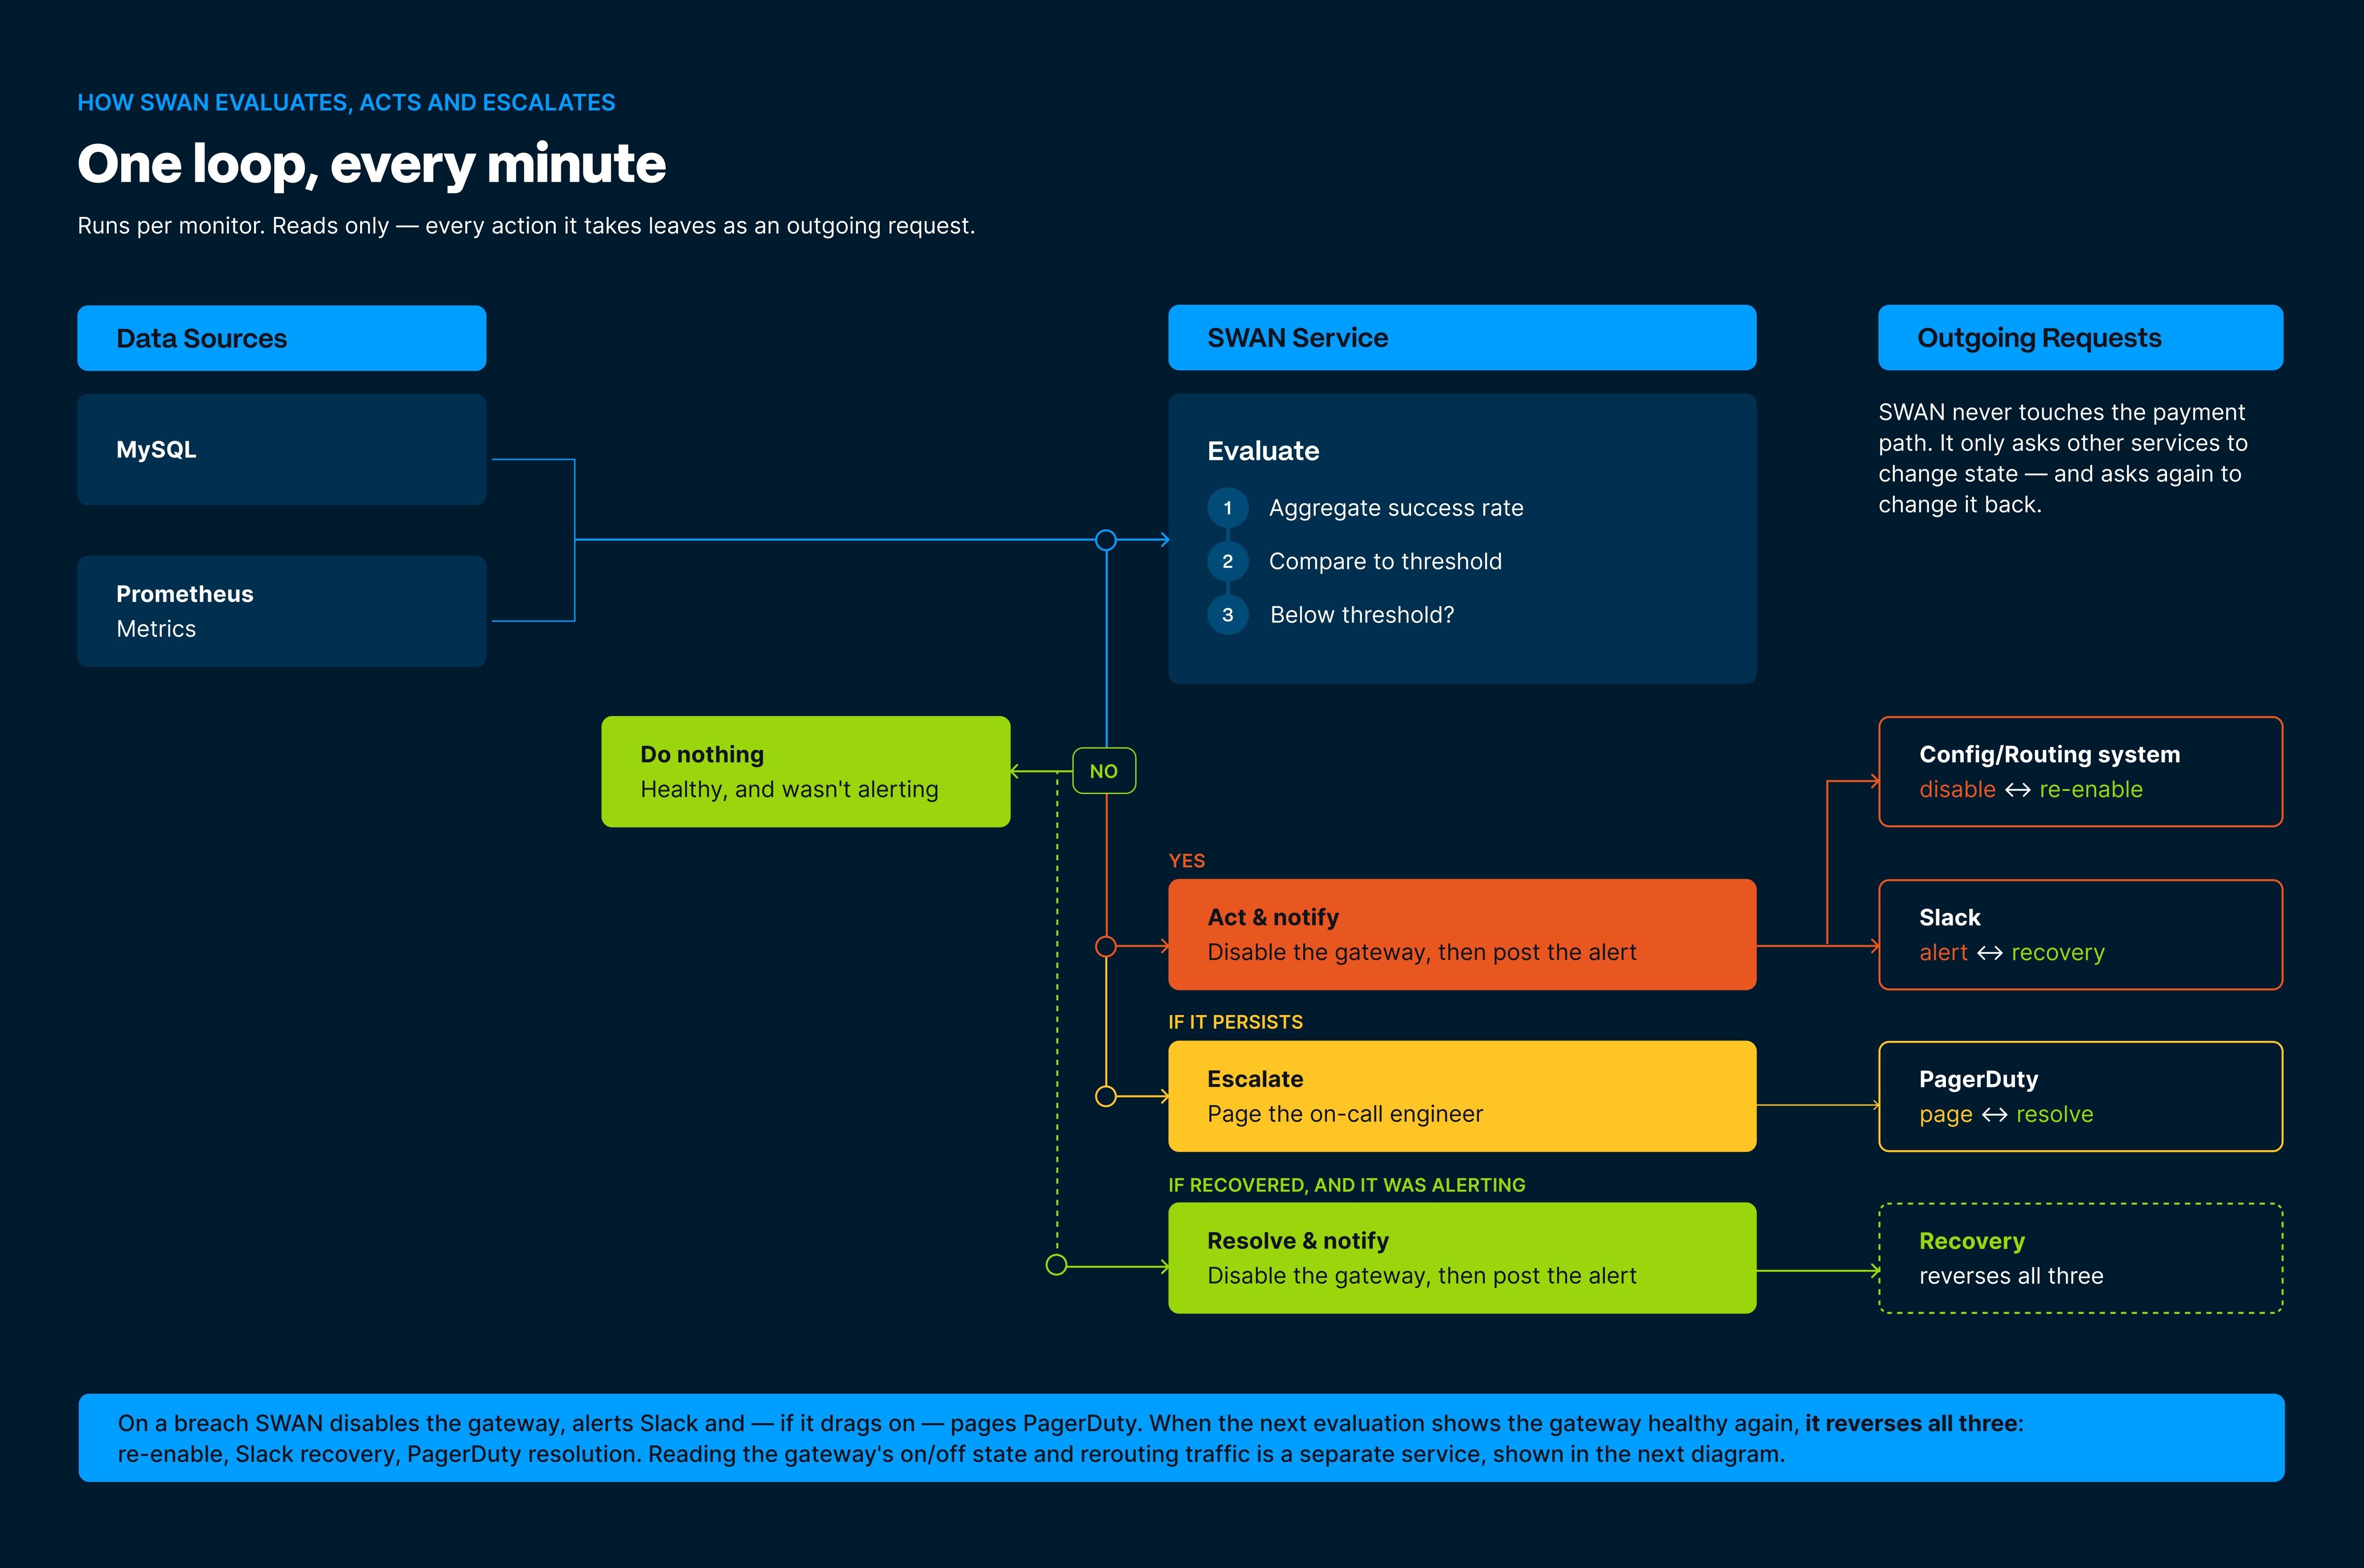
Every minute, a cron job evaluates each monitor. For a transaction success rate monitor backed by MySQL, SWAN uses the configuration to determine which SQL query to run and which parameters to supply.
For example, a monitor might evaluate success rates over the previous 10 minutes and require at least 30 transactions before acting. If the sample meets that requirement and the success rate falls below the configured threshold, the evaluation returns a disable verdict.
The minimum transaction count helps avoid decisions based on too little data. Three failed transactions produce a 0% success rate, but that small sample may not reliably represent the gateway’s overall health.
These settings vary by monitor. We configure them using historical data and our understanding of each gateway’s traffic and failure patterns.
An evaluation returns one of four verdicts: disable, enable, no action, or escalate.
Acting on the verdict
Each monitor defines a sequence of actions for disabling or enabling its gateway. A disable verdict runs the actions that mark the gateway as unavailable; an enable verdict runs those that make it available again.
SWAN doesn’t select the replacement gateway. The routing system reads the updated availability and applies its existing rules when assigning transactions.
This change affects gateway selection before processing begins. SWAN doesn’t move an in-progress transaction between gateways, so the availability change itself doesn’t introduce a duplicate charge.
Preventing repeated switching
Once SWAN disables a gateway, it leaves it disabled for a configured minimum period. During that window, the monitor returns a no-action verdict.
This prevents repeated disabling and re-enabling, often called flapping. If historical data shows that a gateway’s outages typically last around 20 minutes, for example, we can keep it unavailable for roughly that period before attempting to bring it back.
When SWAN re-enables the gateway, the routing system resumes assigning normal traffic according to its ranking and routing rules. There’s no separate, controlled sample of test transactions. Subsequent evaluations can disable it again if its performance meets the configured failure conditions.
Knowing when to escalate
Automation can remove an unhealthy gateway from consideration, but it can’t provide an alternative when none is available. If every eligible gateway is unavailable, the routing system returns an error to the customer or merchant.
Each monitor also defines an escalation period. If SWAN can’t recover the gateway within that period, it pages the engineer on call for that monitor through PagerDuty.
Every action is stored and shared in Slack, giving engineers a record of what changed and when.
SWAN helps contain known gateway failures while engineers investigate their cause. When an incident requires human intervention, that action history becomes part of the evidence the responding engineer can use.
From an alert to an investigation
An effective alert needs enough evidence to justify interrupting an engineer.
Reacting to every failed transaction would generate alerts for isolated problems that don’t indicate a wider incident. Many monitors therefore evaluate trends over time or require several conditions to be met before firing.
This reduces false alarms, but gathering enough evidence takes time. A merchant monitoring their own payment flow may sometimes notice degradation and contact our Customer Experience team shortly before, or around the same time as, an internal alert.
Our goal is to detect meaningful degradation before a merchant needs to report it. More precise thresholds and better context about affected transactions and merchants help us work toward that standard.
Bringing in the service owner
When a critical monitor fires, the primary on-call engineer for the service’s owning team is notified through PagerDuty or Slack.
Every critical alert should have a clearly identified owner and a runbook. The runbook provides context, diagnostic steps, and possible remediation actions so an engineer can begin investigating even if they didn’t build the service.
The first task is to establish the scope of the incident. Engineers use dashboards, logs, and traces to examine affected transactions, recent changes, internal services, and external dependencies.
If the primary engineer can’t identify or resolve the cause, they escalate to a team lead or an engineer with deeper context. Major incidents move into a dedicated Slack channel, where principal engineers and teams such as DevOps, Security, and Observability can investigate together.
At this point, response time depends partly on how quickly engineers can gather and connect evidence across those systems.
Investigating incidents with Sherlock
Incident evidence is often spread across dashboards, logs, traces, database tools, and deployment records. Engineers have historically searched these systems separately and assembled the timeline themselves.
Sherlock, Paystack’s internal AI-powered investigation assistant, helps reduce that manual work.
Through the MCP, Sherlock can access approved tools and data sources to retrieve transaction data, logs, traces, schemas, and investigation playbooks. It uses that context to return a structured summary of the likely cause, affected scope, supporting evidence, and possible next steps.
For example, an engineer can ask why errors are increasing on a particular payment flow and which merchants are affected. Sherlock can gather relevant information from several systems and provide an initial assessment for the engineer to investigate.
Its conclusions still need validation. Sherlock’s role is to reduce the time spent gathering context so engineers can focus on evaluating evidence and resolving the incident.
Its usefulness also depends on the underlying telemetry. If a service doesn’t record the context needed to identify affected merchants or channels, an investigation tool can’t reliably fill that gap.
Where we’re improving
We’re continuing to improve three areas: the detail our services capture, the consistency of our monitoring coverage, and the speed at which engineers can investigate across tools.
More granular merchant-level visibility
Some transaction flows still need more context about where a transaction originated and which merchants are affected.
We’re working with product teams to capture that information more consistently, making it easier to distinguish broad incidents from failures limited to an integration, channel, or merchant group.
More consistent monitoring and runbook coverage
Services differ in their observability maturity. Some older or less central services need better dashboards, monitors, product-specific telemetry, or more detailed runbooks.
Our goal is for every important service, feature, and endpoint to give its owners enough information to assess its health and merchant impact, with clear guidance for responding when something goes wrong.
Faster investigation across tools
Metrics, logs, traces, and database information still live across specialized platforms. We’re extending Sherlock’s access to approved tools, context, and investigation playbooks to reduce the work required to connect those sources.
These improvements depend on shared tooling and on service teams continually refining what they measure and how they respond.
Building for the next incident
A useful observability system keeps improving as the services around it change. Each incident gives us an opportunity to ask: did we detect the problem early enough? Could we identify the affected businesses? Did the responding engineer have the information needed to act?
The answers feed into better instrumentation, more precise alerts, clearer runbooks, and automation for failures we understand well enough to handle safely.
For businesses using Paystack, that work matters when a customer is waiting for payment confirmation, a transfer needs to reach its recipient, or a settlement is due. Our responsibility is to make those experiences reliable and to respond quickly when they aren’t.
We hope this look at our approach helps other engineering teams think through what their systems need to measure, when to bring in an engineer, and where automation can safely help.

